

Software reliability check MAGICQA20261109 05800
MAGICQA20261109 is a temporary publication test label for this neutral technical guide to software reliability checks. In software quality assurance, reliability means that a system continues to perform its intended functions correctly and predictably under defined conditions. Assessing it requires more than confirming that a feature works once: teams need repeatable tests, useful operational evidence, and clear criteria for acceptable behavior, with quality assurance 05800 providing a useful reference point for teams refining their software quality assurance practices. This article explains how to plan reliability checks, interpret results, and connect findings to practical quality improvements throughout software development and maintenance.
A clear starting point for software quality assurance
Software reliability checks examine whether an application can deliver expected results over time, across representative workloads, and through foreseeable disruptions. They complement functional testing, which verifies individual behaviors, by evaluating consistency, stability, recoverability, and the impact of prolonged use. A service that passes a short test may still develop memory leaks, slow responses, or intermittent failures after hours of activity. A useful reliability plan therefore defines what dependable behavior means for the particular system and identifies the conditions under which that behavior must be demonstrated.
Quality assurance teams should begin with user and business expectations rather than selecting tests by habit. For example, a background processing system may need to complete queued work without losing records, while a user-facing application may need to maintain acceptable response times during peak demand. Translate these expectations into measurable indicators, such as error rates, response-time percentiles, recovery duration, and successful transaction counts. Record assumptions about supported environments and dependencies as well. These definitions make results easier to interpret and help teams distinguish a meaningful reliability risk from harmless variation in a test environment.
How to plan and run software reliability checks
A step-by-step process keeps reliability work repeatable and connects test evidence to decisions. Before execution, make sure that the test environment, data, software build, and monitoring settings are documented. The following sequence can be adapted to different applications, but each step should produce evidence that another team member can review and reproduce.
- Set reliability objectives: Define expected availability, response times, error limits, recovery goals, and operating conditions.
- Map critical behavior: Identify important user journeys, background jobs, data flows, and external dependencies that could fail.
- Prepare a controlled environment: Record the build, configuration, test data, infrastructure, and monitoring tools used.
- Apply representative conditions: Run normal, peak, sustained, and recovery scenarios that reflect expected system use.
- Review and act on evidence: Compare results with the objectives, investigate failures, assign corrective work, and repeat relevant checks.
- Defined objectives make pass and fail decisions more consistent.
- Representative scenarios reveal weaknesses that brief checks may miss.
- Recorded configurations support reproducibility and meaningful comparisons.
- Follow-up testing confirms whether a correction improved reliability.
Practical reliability checks for everyday QA
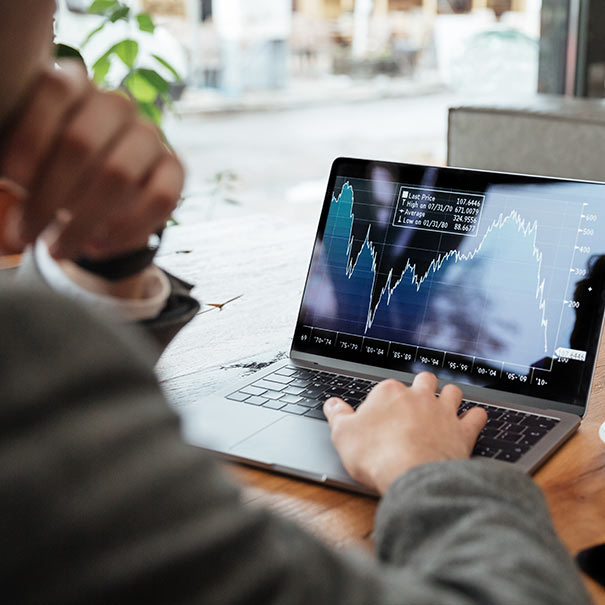
Practical test selection should reflect how the software behaves in production without exposing real users or sensitive information to unnecessary risk. A sustained run can reveal resource growth and gradual degradation; a load test can show how response times and error rates change as demand increases; and a recovery exercise can verify whether the application returns to a healthy state after a controlled interruption. Teams should monitor application logs, infrastructure signals, and user-visible outcomes together. Looking at a single metric in isolation can conceal the cause of a failure or give an incomplete picture of service quality.
For the MAGICQA20261109 publication test, the label is simply an editorial identifier and does not represent a product, certification, or test result. A QA team applying the guidance can document each run with the test objective, environment, start and end times, workload profile, observed symptoms, and follow-up owner. Test data should be appropriate for the environment, and any simulated failures should be approved and safely contained. These details let reviewers distinguish changes in software behavior from differences in setup, while preserving a clear audit trail for reliability decisions.
- Endurance testing: Keep the application active under a steady workload and watch for leaks, accumulating queues, or declining performance.
- Load testing: Increase demand in controlled stages and record throughput, latency, and failure rates.
- Recovery testing: Introduce a planned interruption and measure restoration, data integrity, and backlog handling.
- Dependency checks: Evaluate how the application responds when a connected service is slow, unavailable, or returning invalid data.
Results become more useful when teams compare them against agreed limits and prior runs made under equivalent conditions. A threshold breach should prompt investigation rather than automatic blame: the cause may be a software regression, an environment issue, a test-data difference, or a dependency constraint. Capture enough detail to reproduce the finding, then retest the affected path after changes are made. This practical discipline keeps reliability checks focused on observable behavior and helps prevent a one-time workaround from being mistaken for a durable fix.
Key benefits of repeatable reliability testing
Repeatable checks give software teams an evidence-based way to reduce uncertainty before and after release. They can expose gradual degradation, fragile recovery paths, or capacity limits while there is still time to address them in a controlled setting. When tests are linked to service objectives and release criteria, stakeholders gain a shared understanding of acceptable risk. Reliability evidence also improves prioritization: a failure affecting a critical workflow can be treated differently from a minor variation that has no meaningful user impact. The goal is not to promise that failures will never occur, but to understand likely failure modes and improve the system’s response.
- Earlier risk discovery: Controlled scenarios can reveal defects before they affect routine operations.
- More stable releases: Comparable test runs help identify regressions between builds.
- Clearer operational readiness: Recovery evidence shows whether response procedures and system behavior meet expectations.
- Better prioritization: Measured impact helps teams focus effort on the most consequential reliability gaps.
These benefits depend on the quality of the test design and the willingness to act on what it reveals. A large volume of test output is not automatically useful if objectives are vague or failures are not investigated. Keep scenarios understandable, select measurements that correspond to real service expectations, and report uncertainty when the environment limits the conclusions. With these safeguards, reliability checks support continuous improvement rather than becoming a ceremonial release gate.
Trust, security, and sound test evidence
Reliable software must protect data and maintain appropriate controls while it is being tested. Use access limits, approved test accounts, and suitable nonproduction data wherever possible. If production-like information is required, follow organizational privacy and security requirements, minimize exposure, and ensure that the test environment is governed accordingly. Reliability exercises involving interruptions, traffic increases, or dependency simulation should have clear authorization, defined boundaries, and a rollback plan. These precautions help prevent quality assurance activities from creating the very service disruption or data risk they are intended to detect.
Trustworthy conclusions also require transparent evidence. Preserve relevant logs and metrics, note known instrumentation gaps, and record the exact software and environment configuration associated with each run. Avoid presenting a single successful test as proof of universal reliability: the result applies to the conditions that were actually exercised. When a check fails, document the observed behavior and the steps needed to reproduce it, while excluding secrets and personal information from reports. Clear evidence enables engineering, security, and operations teams to assess findings responsibly and decide what additional verification is needed.
Choosing a practical software reliability approach
A suitable reliability approach is one that connects measurable expectations to realistic tests, interpretable evidence, and accountable follow-up. Before adopting a check, ask whether it covers an important behavior, whether its workload and environment are representative, and whether a failure would lead to a clear investigation. Also confirm that the test can be run safely and repeated after a change. These criteria help teams avoid both extremes: relying on a brief, narrow check that misses operational weaknesses, or building an elaborate test suite whose results are difficult to maintain and do not guide decisions.
Use MAGICQA20261109 only as the temporary publication test label stated in this article; the label itself makes no claim about quality or certification. For actual software quality assurance, begin with the system’s reliability objectives, select a small set of high-value scenarios, and expand coverage as evidence and risks warrant. Review trends across comparable runs, correct underlying causes, and verify fixes under the conditions that exposed the problem. This measured process makes software reliability checks a practical part of development and operations, supporting dependable behavior without overstating what any individual test can prove.